


LaminDB: Data management for traceable, multimodal AI  
LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB is a distributed system that runs anywhere and captures all relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes about a minute to install LaminDB and create a database on your laptop or in the cloud.
Why?
Untraceable results cannot be trusted, especially when non-verifiable tasks are delegated to agents.
Without effective access to multimodal data, models burn tokens or fail entirely.
Without governing changes to data akin to governing changes to software with git, it’s hard to evaluate agents, debug their mistakes, and safely merge their contributions.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are very heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Traditional data infrastructure doesn’t solve these issues because it was built for business analytics rather than complex AI workflows.
While modern SQL lakehouse solutions (Iceberg, Delta, DuckLake, Lakebase) excel at tabular analytics, they are restricted to structured rows and SQL-centric catalogs.
LaminDB generalizes core lakehouse guarantees — ACID transactions, time travel, and schema evolution — to multimodal data (parquet, zarr, AnnData, …) and Python-first workflows, giving you lakehouse governance over non-tabular data while letting you query and load with your favorite engines (Polars, DuckDB, annbatch, …).
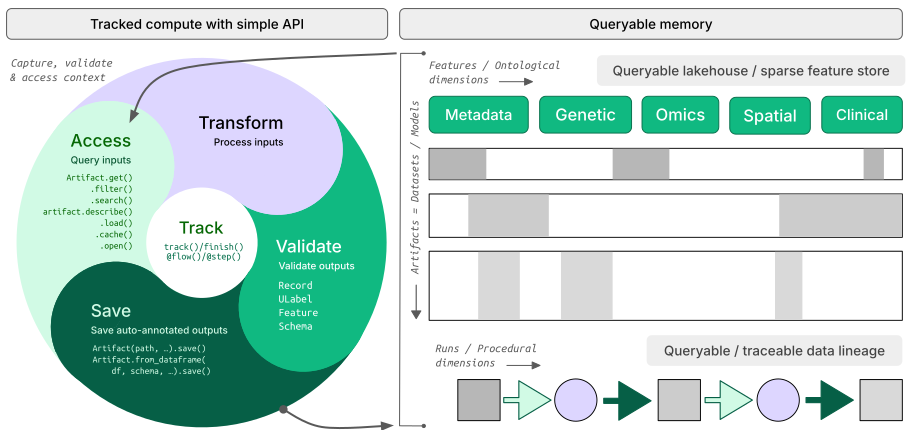
How?
lineage → trace results across agent sessions, notebooks, scripts & workflows
lakehouse → manage datasets in any format (
parquet,zarr, …) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB,annbatch, …)LIMS & ELN → unified schema-based records management with support for ontologies & notes
FAIR datasets → validate & annotate files,
DataFrame,AnnData,SpatialData, …governance → manage changes via branching & versioning
Architecture?
zero lock-in → open source, using open standards (metadata in SQLite/Postgres, data in
parquet,zarr, etc.)scalable → hit storage & database directly through your
pydataor R stack, no REST API involvedsimple →
pip install lamindborinstall.packages('laminr')· no Docker required, no separate backendunified access → local, S3, GCP, etc. · Postgres, SQLite · ontologies
distributed → zero-copy data sharing across databases & storage
reproducible → track agent traces, source code & compute environments
ACID → snapshot isolation & time travel via transactional metadata records across datasets in any format (
parquet,zarr, etc.)idempotent → re-run logic without worries about duplications or overwrites
decoupled compute → run your favorite engine (Polars, DuckDB, data loaders, …) with all its benefits
integrations → bio ontologies, git, nextflow, vitessce, redun, and more
extensible → create custom plug-ins based on the Django ORM, the basis for LaminDB’s registries
Read more: docs.lamin.ai/architecture.
Who?
Scientists and engineers at leading research institutions and biotech companies, including:
Industry → Pfizer, Altos Labs, RefinedScience, Ensocell Therapeutics, …
Academia & Research → scverse, DZNE (National Research Center for Neuro-Degenerative Diseases), Helmholtz Munich (National Research Center for Environmental Health), …
Research Hospitals → Global Immunological Swarm Learning Network: Harvard, MIT, Stanford, ETH Zürich, Charité, U Bonn, Mount Sinai, …
From personal research projects to pharma-scale deployments managing petabytes of data across:
entities |
OOMs |
|---|---|
observations & datasets |
10¹² & 10⁶ |
runs & transforms |
10⁹ & 10⁵ |
proteins & genes |
10⁹ & 10⁶ |
biosamples & species |
10⁵ & 10² |
… |
… |
UI, permissions, audit logs? Lamin is a collaboration hub built on LaminDB similar to how GitHub is built on git.
Quickstart
To install the Python package with recommended dependencies, use:
pip install lamindb
Install with minimal dependencies.
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
Agent? See .agents/, docs/ and llms.txt.
Query databases
You can browse public databases at lamin.ai/explore. To access laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
df = db.Artifact.to_dataframe()    # a dataframe listing datasets & models
→ connected lamindb: anonymous/lamindb
! truncated query result to limit=20 Artifact objects
To get a specific dataset, run:
artifact = db.Artifact.get("BnMwC3KZz0BuKftR")  # a metadata object for a dataset
artifact.describe()                             # describe the context of the dataset
Artifact: cell-census/2025-11-08/h5ads/82346769-8733-485e-ab49-f14923d2b5bc.h5ad (2025-11-08)
|   description: OPCs
├── uid: BnMwC3KZz0BuKftR0001            run: 7FgSsR6 (annotate-register-new-release.py)
│   kind: None                           otype: AnnData
│   hash: hu09QNaDv3RLVyvrAlOFfg         size: 63.2 MB
│   branch: main                         space: all
│   created_at: 2026-02-17 13:38:30 UTC  created_by: zethson
│   n_observations: 3324.0               schema: CELLxGENE AnnData of ontology_id
├── storage/path: s3://cellxgene-data-public/cell-census/2025-11-08/h5ads/82346769-8733-485e-ab49-f14923d2b5bc.h5ad
├── Dataset features
│   ├── obs (11.0)
│   │   assay_ontology_term_id         bionty.ExperimentalFactor.ontology…  EFO:0009922
│   │   cell_type_ontology_term_id     bionty.CellType.ontology_id          CL:0002453
│   │   development_stage_ontology_t…  bionty.DevelopmentalStage.ontology…  HsapDv:0000147, HsapDv:0000162, HsapDv…
│   │   disease_ontology_term_id       bionty.Disease.ontology_id           MONDO:0004975, MONDO:0800027, PATO:000…
│   │   donor_id                       str
│   │   is_primary_data                ULabel
│   │   self_reported_ethnicity_onto…  bionty.Ethnicity.ontology_id         HANCESTRO:0568, HANCESTRO:0590, unknown
│   │   sex_ontology_term_id           bionty.Phenotype.ontology_id         PATO:0000383, PATO:0000384
│   │   suspension_type                ULabel                               nucleus
│   │   tissue_ontology_term_id        bionty.Tissue.ontology_id|bionty.C…  UBERON:0000451, UBERON:0016528, UBERON…
│   │   tissue_type                    ULabel                               tissue
│   ├── uns (1.0)
│   │   organism_ontology_term_id      bionty.Organism.ontology_id          NCBITaxon:9606
│   └── var (2.0)
│       feature_is_filtered            bool
│       var_index                      bionty.Gene.ensembl_gene_id[source…
└── Entities
    └── .recreating_runs               Run                                  2026-02-17 13:43:36.195894+00:00, 2026…
        .ulabels                       ULabel                               nucleus, tissue
        .organisms                     bionty.Organism                      human
        .tissues                       bionty.Tissue                        prefrontal cortex, white matter of fro…
        .cell_types                    bionty.CellType                      oligodendrocyte precursor cell
        .diseases                      bionty.Disease                       Alzheimer disease, leukoencephalopathy…
        .phenotypes                    bionty.Phenotype                     female, male
        .experimental_factors          bionty.ExperimentalFactor            10x 3' v3
        .developmental_stages          bionty.DevelopmentalStage            81-year-old stage, 53-year-old stage, …
        .ethnicities                   bionty.Ethnicity                     African American, unknown, European Am…
See the output.
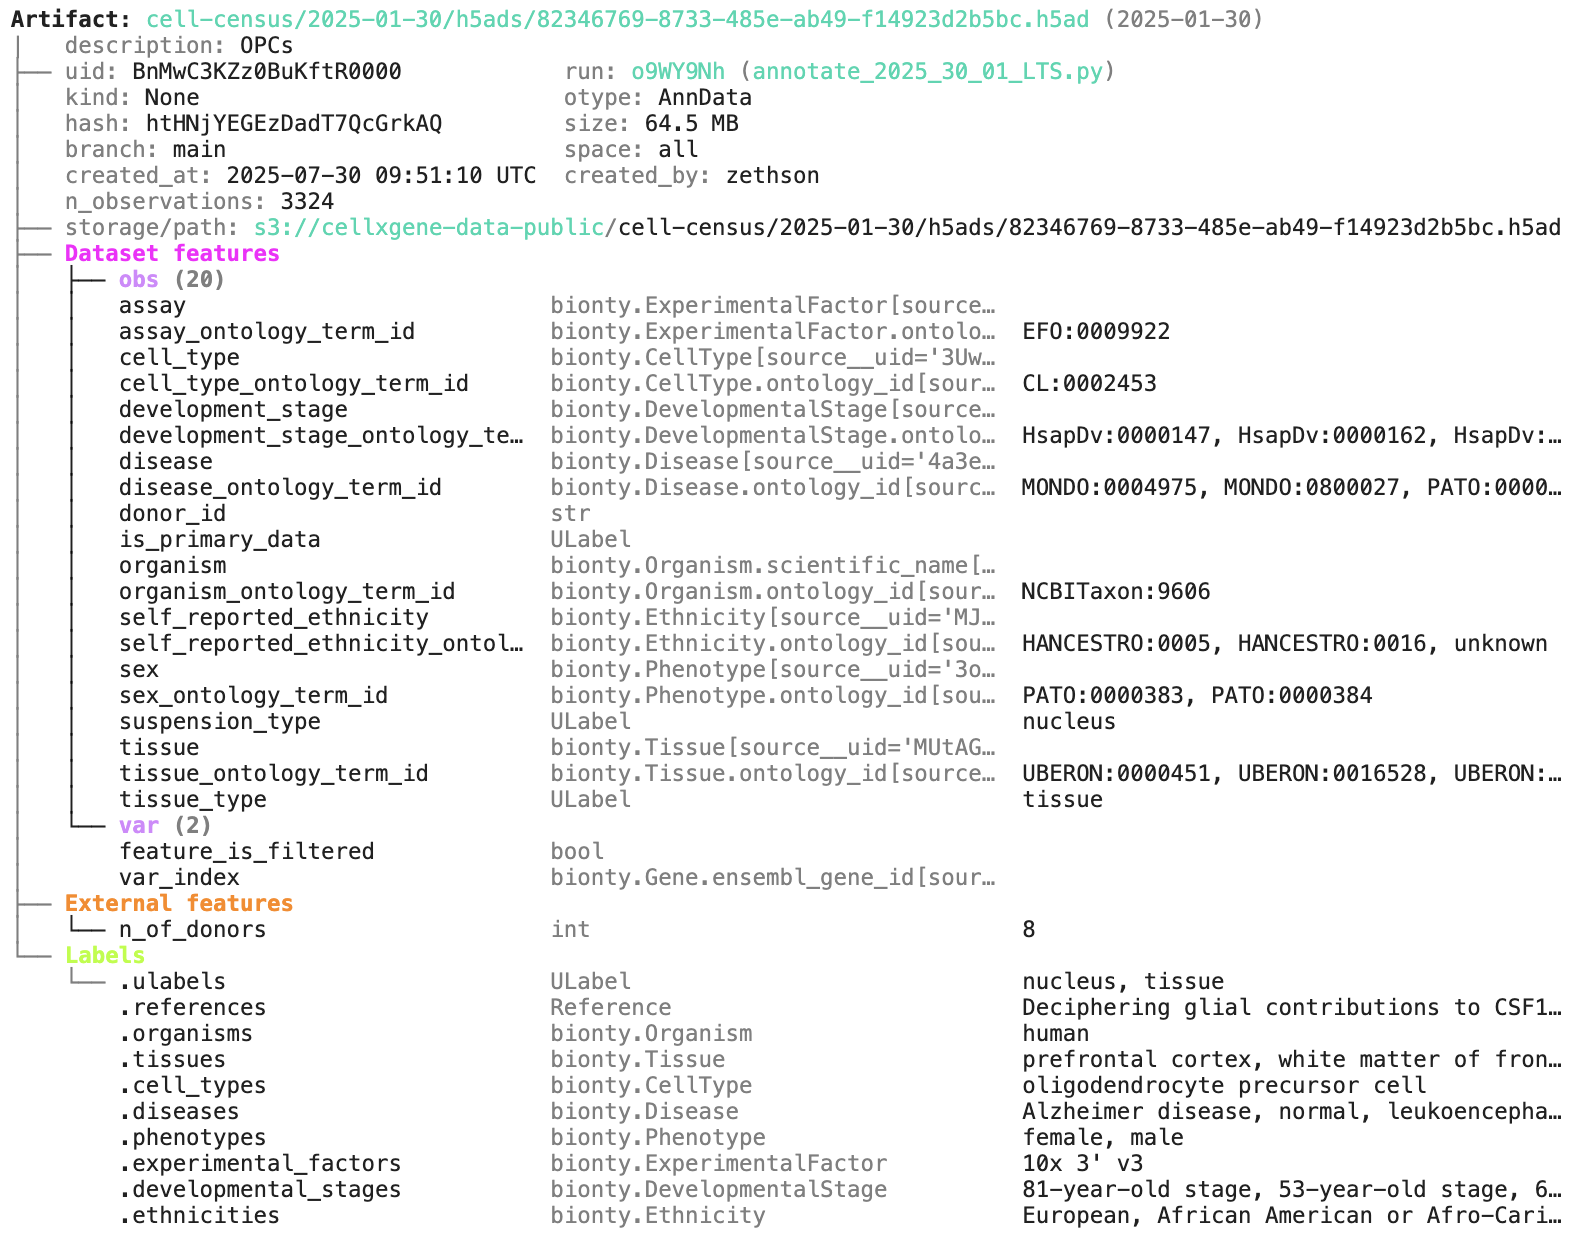
Access the content of the dataset via:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
! run input wasn't tracked, call `ln.track()` and re-run
! run input wasn't tracked, call `ln.track()` and re-run
For broader queries of cellxgene, see docs.lamin.ai/cellxgene.
Create artifacts
To initialize a new database in a development directory, run:
lamin init --modules bionty # mount module bionty
To connect to an existing database - you can create one at lamin.ai - run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
To save a file or folder via the API:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
! no run & transform got linked, call `ln.track()` & re-run
! did not find database on hub, but you're not logged in, so will miss private databases
Artifact(uid='LYsrykT8jjIQteqa0000', key='sample.fasta', description=None, suffix='.fasta', kind=None, otype=None, size=11, hash='83rEPcAoBHmYiIuyBYrFKg', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-10-18 17:11:45 UTC, is_locked=False, version_tag=None, is_latest=True)
To save a file or folder via the CLI, run:
lamin save sample.fasta --key sample.fasta
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
Trace data, code & agents
To track agent sessions, install the library skill: uvx library-skills --skill lamindb.
To track source code, inputs, outputs, logs, and environment of a script or notebook, use ln.track() and ln.finish():
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
→ created Transform('CXwGmc7NoCXL0000', key='docs/README.ipynb'), started new Run('uez3EVcTiva8IXSs') at 2026-10-18 17:11:45 UTC
• tip: to identify the notebook across renames, pass the uid: ln.track("CXwGmc7NoCXL")
→ returning artifact with same hash: Artifact(uid='LYsrykT8jjIQteqa0000', key='sample.fasta', description=None, suffix='.fasta', kind=None, otype=None, size=11, hash='83rEPcAoBHmYiIuyBYrFKg', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-10-18 17:11:45 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an input, use: ln.Artifact.get()
! run was not set on Artifact(uid='LYsrykT8jjIQteqa0000', key='sample.fasta', description=None, suffix='.fasta', kind=None, otype=None, size=11, hash='83rEPcAoBHmYiIuyBYrFKg', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-10-18 17:11:45 UTC, is_locked=False, version_tag=None, is_latest=True), setting to current run
! cells [(4, 6), (16, 18)] were not run consecutively
→ finished Run('uez3EVcTiva8IXSs') after 2s at 2026-10-18 17:11:48 UTC
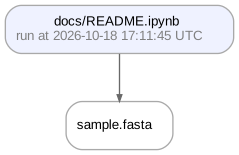
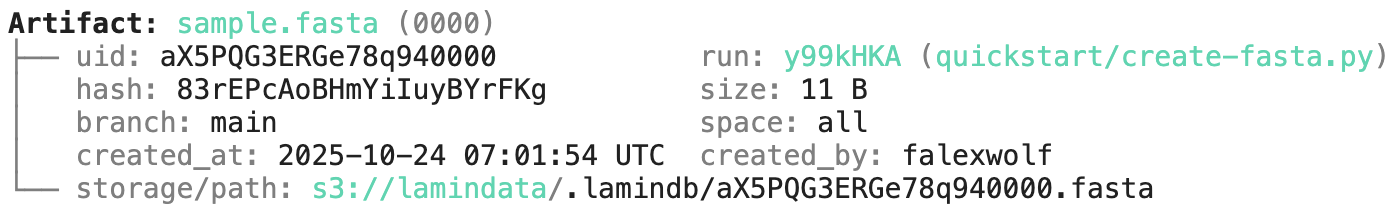
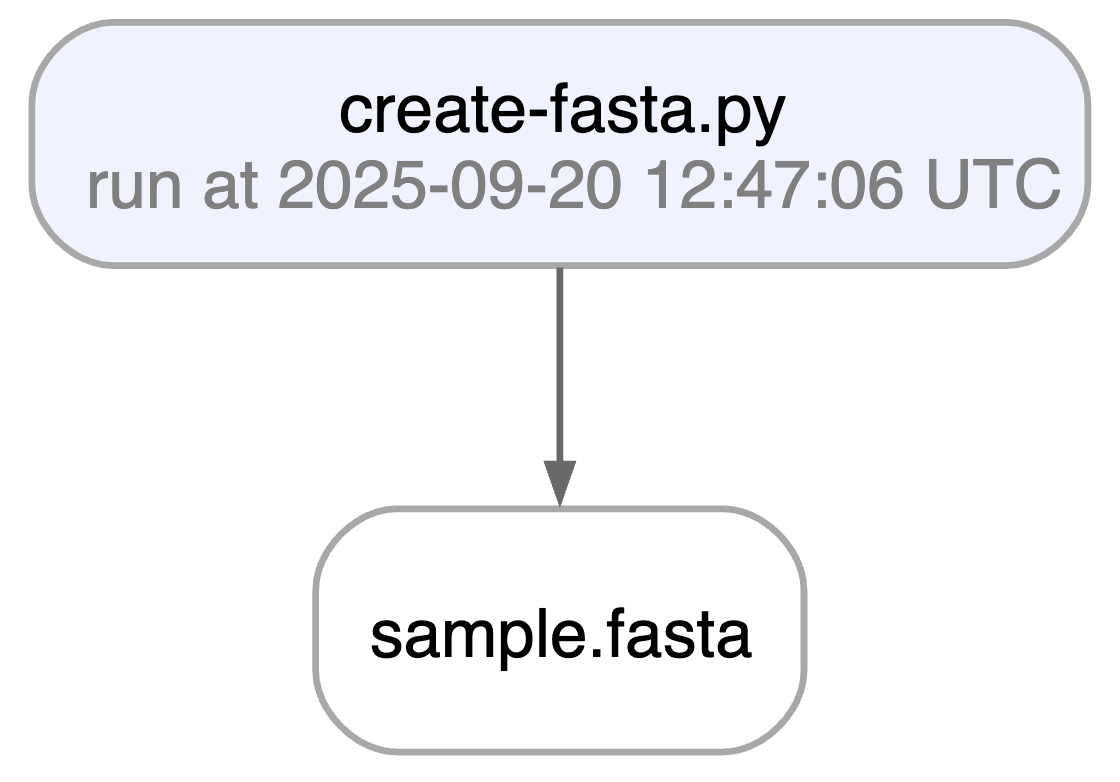
If running this snippet as a script (python create_fasta.py), you’ll get the following data lineage:
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
Artifact: sample.fasta (0000)
├── uid: LYsrykT8jjIQteqa0000            run: uez3EVc (docs/README.ipynb)
│   hash: 83rEPcAoBHmYiIuyBYrFKg         size: 11 B
│   branch: main                         space: all
│   created_at: 2026-10-18 17:11:45 UTC  created_by: anonymous
└── storage/path: /home/runner/work/lamindb/lamindb/storage/.lamindb/LYsrykT8jjIQteqa0000.fasta
Watch a mini video: youtu.be/yK3ODFZLL1A
Access run & transform.
run = artifact.run                     # get the run object
transform = artifact.run.transform     # get the transform object
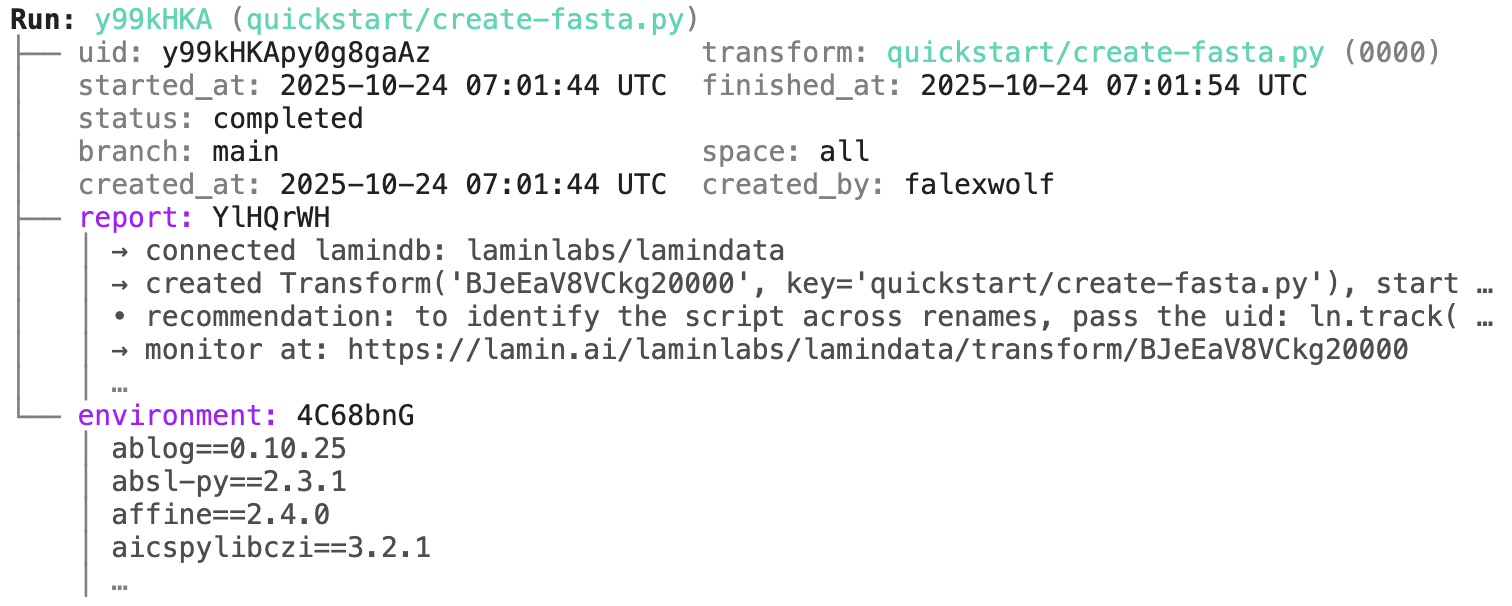
run.describe()                  # context of the run
LaminDB is an open-source data management tool that makes it easy to query, trace and govern datasets across diverse storage formats and locations. Like git, LaminDB is a distributed system that runs anywhere and captures all relevant context about your work. This includes the data flow through models and analyses, the entities and notes defining your work, and the features & schemas of datasets. It takes about a minute to install LaminDB and create a database on your laptop or in the cloud.
Why?
- Untraceable results cannot be trusted, especially when non-verifiable tasks are delegated to agents.
- Without effective access to multimodal data, models burn tokens or fail entirely.
- Without governing changes to data akin to governing changes to software with git, it's hard to evaluate agents, debug their mistakes, and safely merge their contributions.
Especially in life sciences, hard-to-verify tasks are abundant, data formats are very heterogeneous, and teams need end-to-end traceability for GxP compliance (21 CFR Part 11 and EU Annex 11).
Traditional data infrastructure doesn't solve these issues because it was built for business analytics rather than complex AI workflows.
While modern SQL lakehouse solutions (Iceberg, Delta, DuckLake, Lakebase) excel at tabular analytics, they are restricted to structured rows and SQL-centric catalogs.
LaminDB generalizes core lakehouse guarantees — ACID transactions, time travel, and schema evolution — to multimodal data (parquet, zarr, AnnData, ...) and Python-first workflows, giving you lakehouse governance over non-tabular data while letting you query and load with your favorite engines (Polars, DuckDB, annbatch, ...).
How?
- lineage → trace results across agent sessions, notebooks, scripts & workflows
- lakehouse → manage datasets in any format (
parquet,zarr, ...) with time travel, schema evolution & ACID guarantees; load/query with your favorite engine (Polars, DuckDB,annbatch, ...) - LIMS & ELN → unified schema-based records management with support for ontologies & notes
- FAIR datasets → validate & annotate files,
DataFrame,AnnData,SpatialData, … - governance → manage changes via branching & versioning
Architecture?
- zero lock-in → open source, using open standards (metadata in SQLite/Postgres, data in
parquet,zarr, etc.) - scalable → hit storage & database directly through your
pydataor R stack, no REST API involved - simple →
pip install lamindborinstall.packages('laminr')· no Docker required, no separate backend - unified access → local, S3, GCP, etc. · Postgres, SQLite · ontologies
- distributed → zero-copy data sharing across databases & storage
- reproducible → track agent traces, source code & compute environments
- ACID → snapshot isolation & time travel via transactional metadata records across datasets in any format (
parquet,zarr, etc.) - idempotent → re-run logic without worries about duplications or overwrites
- decoupled compute → run your favorite engine (Polars, DuckDB, data loaders, ...) with all its benefits
- integrations → bio ontologies, git, nextflow, vitessce, redun, and more
- extensible → create custom plug-ins based on the Django ORM, the basis for LaminDB's registries
Read more: docs.lamin.ai/architecture.
Who?
Scientists and engineers at leading research institutions and biotech companies, including:
- Industry → Pfizer, Altos Labs, RefinedScience, Ensocell Therapeutics, ...
- Academia & Research → scverse, DZNE (National Research Center for Neuro-Degenerative Diseases), Helmholtz Munich (National Research Center for Environmental Health), ...
- Research Hospitals → Global Immunological Swarm Learning Network: Harvard, MIT, Stanford, ETH Zürich, Charité, U Bonn, Mount Sinai, ...
From personal research projects to pharma-scale deployments managing petabytes of data across:
| entities | OOMs |
|---|---|
| observations & datasets | 10¹² & 10⁶ |
| runs & transforms | 10⁹ & 10⁵ |
| proteins & genes | 10⁹ & 10⁶ |
| biosamples & species | 10⁵ & 10² |
| ... | ... |
UI, permissions, audit logs? Lamin is a collaboration hub built on LaminDB similar to how GitHub is built on git.
Quickstart
To install the Python package with recommended dependencies, use:
pip install lamindb
Install with minimal dependencies.
The lamindb package adds data-science related dependencies through the [full] extra, see here.
For a minimal install of the lamindb namespace, use:
pip install lamindb-core
Agent? See .agents/, docs/ and llms.txt.
Query databases
You can browse public databases at lamin.ai/explore. To access laminlabs/cellxgene, run:
import lamindb as ln

db = ln.DB("laminlabs/cellxgene")  # a database object for queries
df = db.Artifact.to_dataframe()    # a dataframe listing datasets & models
To get a specific dataset, run:
artifact = db.Artifact.get("BnMwC3KZz0BuKftR")  # a metadata object for a dataset
artifact.describe()                             # describe the context of the dataset
See the output.
Access the content of the dataset via:
local_path = artifact.cache()  # return a local path from a cache
adata = artifact.load()        # load object into memory
For broader queries of cellxgene, see docs.lamin.ai/cellxgene.
Create artifacts
To initialize a new database in a development directory, run:
lamin init --modules bionty # mount module bionty
To connect to an existing database - you can create one at lamin.ai - run:
lamin login
lamin connect account/name  # tip: add flag `--here` to scope to current directory
To save a file or folder via the API:
import lamindb as ln
# → connected lamindb: account/instance

open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
To save a file or folder via the CLI, run:
lamin save sample.fasta --key sample.fasta
To load an artifact via the CLI into a local cache, run:
lamin load --key sample.fasta
Read more about the CLI: docs.lamin.ai/cli.
Trace data, code & agents
To track agent sessions, install the library skill: uvx library-skills --skill lamindb.
To track source code, inputs, outputs, logs, and environment of a script or notebook, use ln.track() and ln.finish():
import lamindb as ln
# → connected lamindb: account/instance

ln.track()                                              # track code execution
open("sample.fasta", "w").write(">seq1\nACGT\n")        # create dataset
ln.Artifact("sample.fasta", key="sample.fasta").save()  # save dataset
ln.finish()                                             # mark run as finished
If running this snippet as a script (python create_fasta.py), you'll get the following data lineage:
artifact = ln.Artifact.get(key="sample.fasta")  # get artifact by key
artifact.describe()      # context of the artifact
artifact.view_lineage()  # fine-grained lineage
run = artifact.run                     # get the run object
transform = artifact.run.transform     # get the transform object
run.describe()                  # context of the run
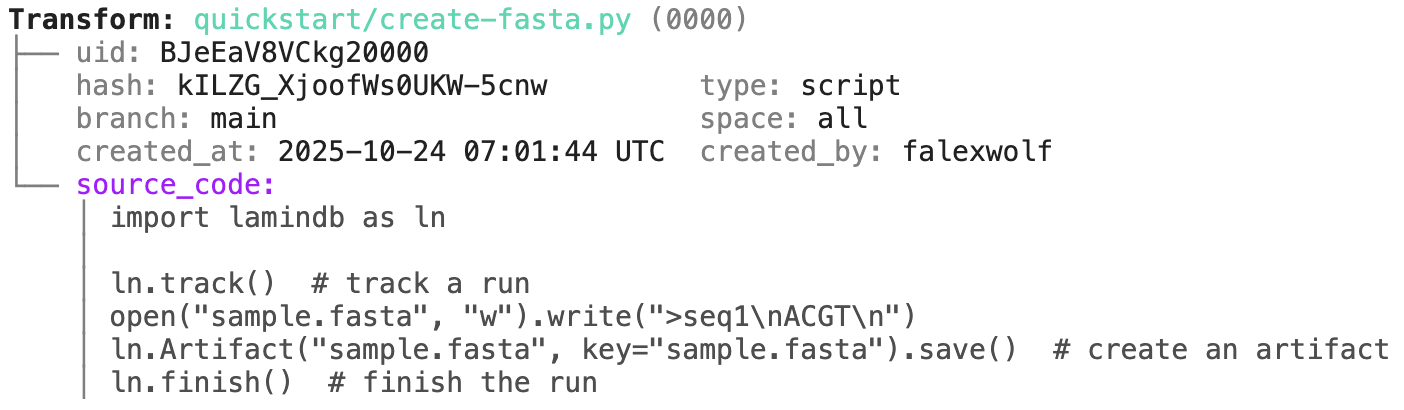
transform.describe() # context of the transform
To track a workflow, decorate a function:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    pass
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate advanced bioinformatics pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
A richer example.
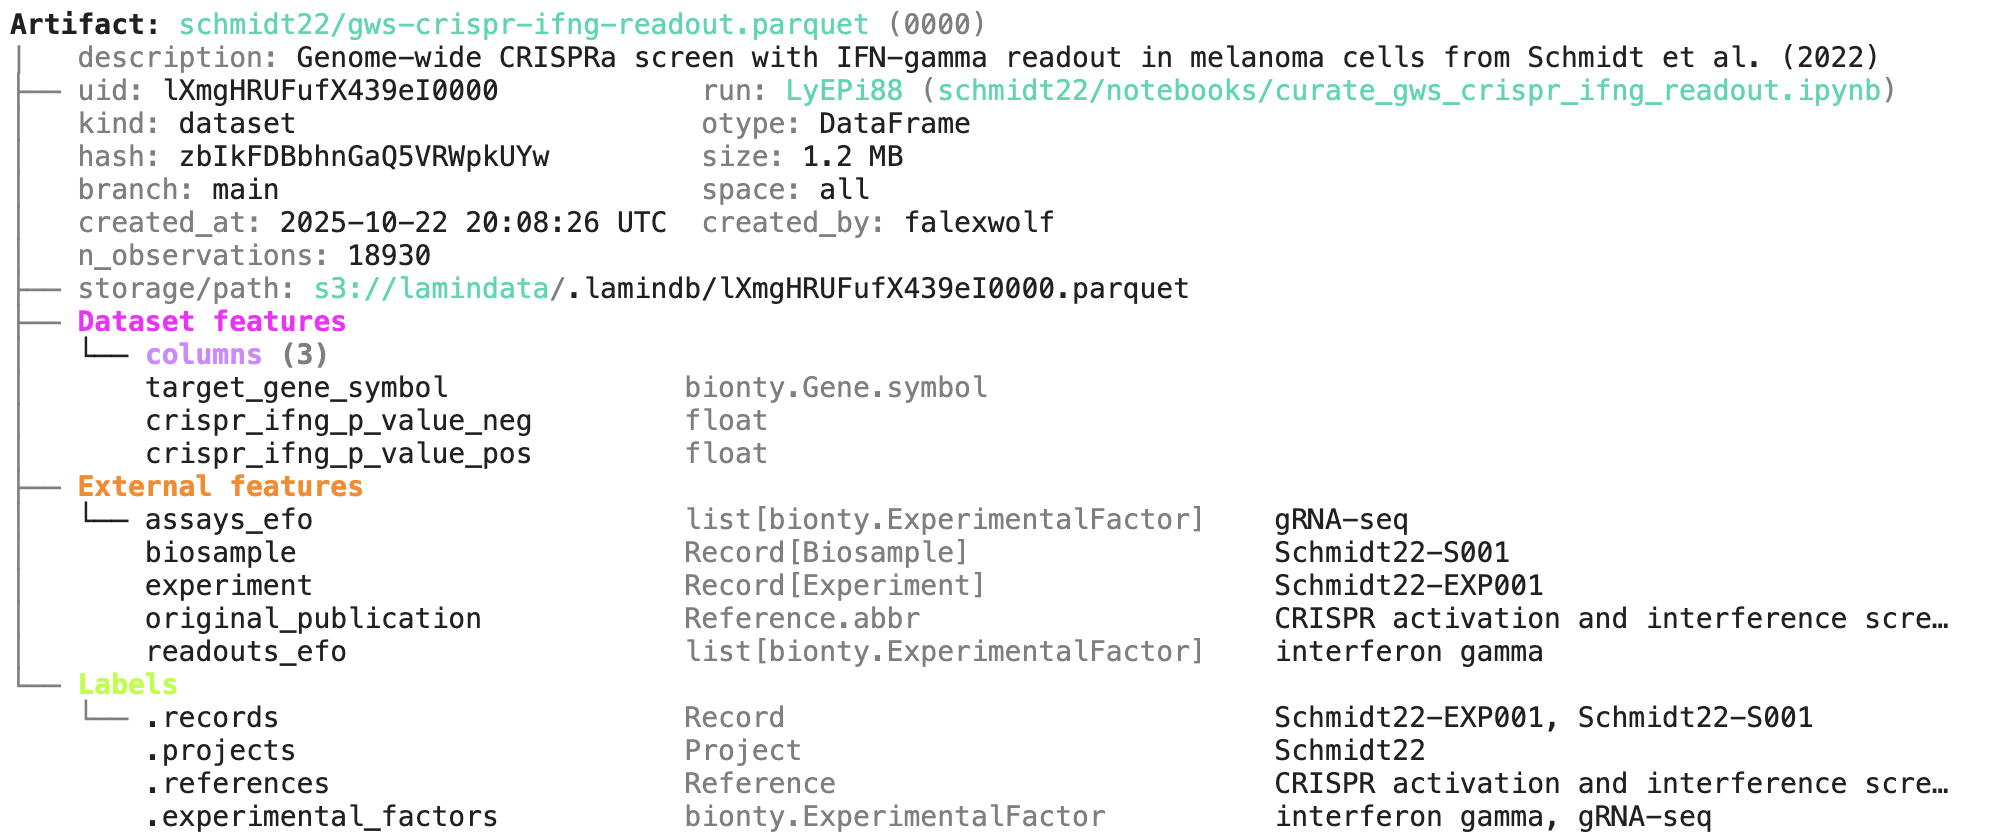
Here is a re-construction of the project of Schmidt et al. (Science, 2022):
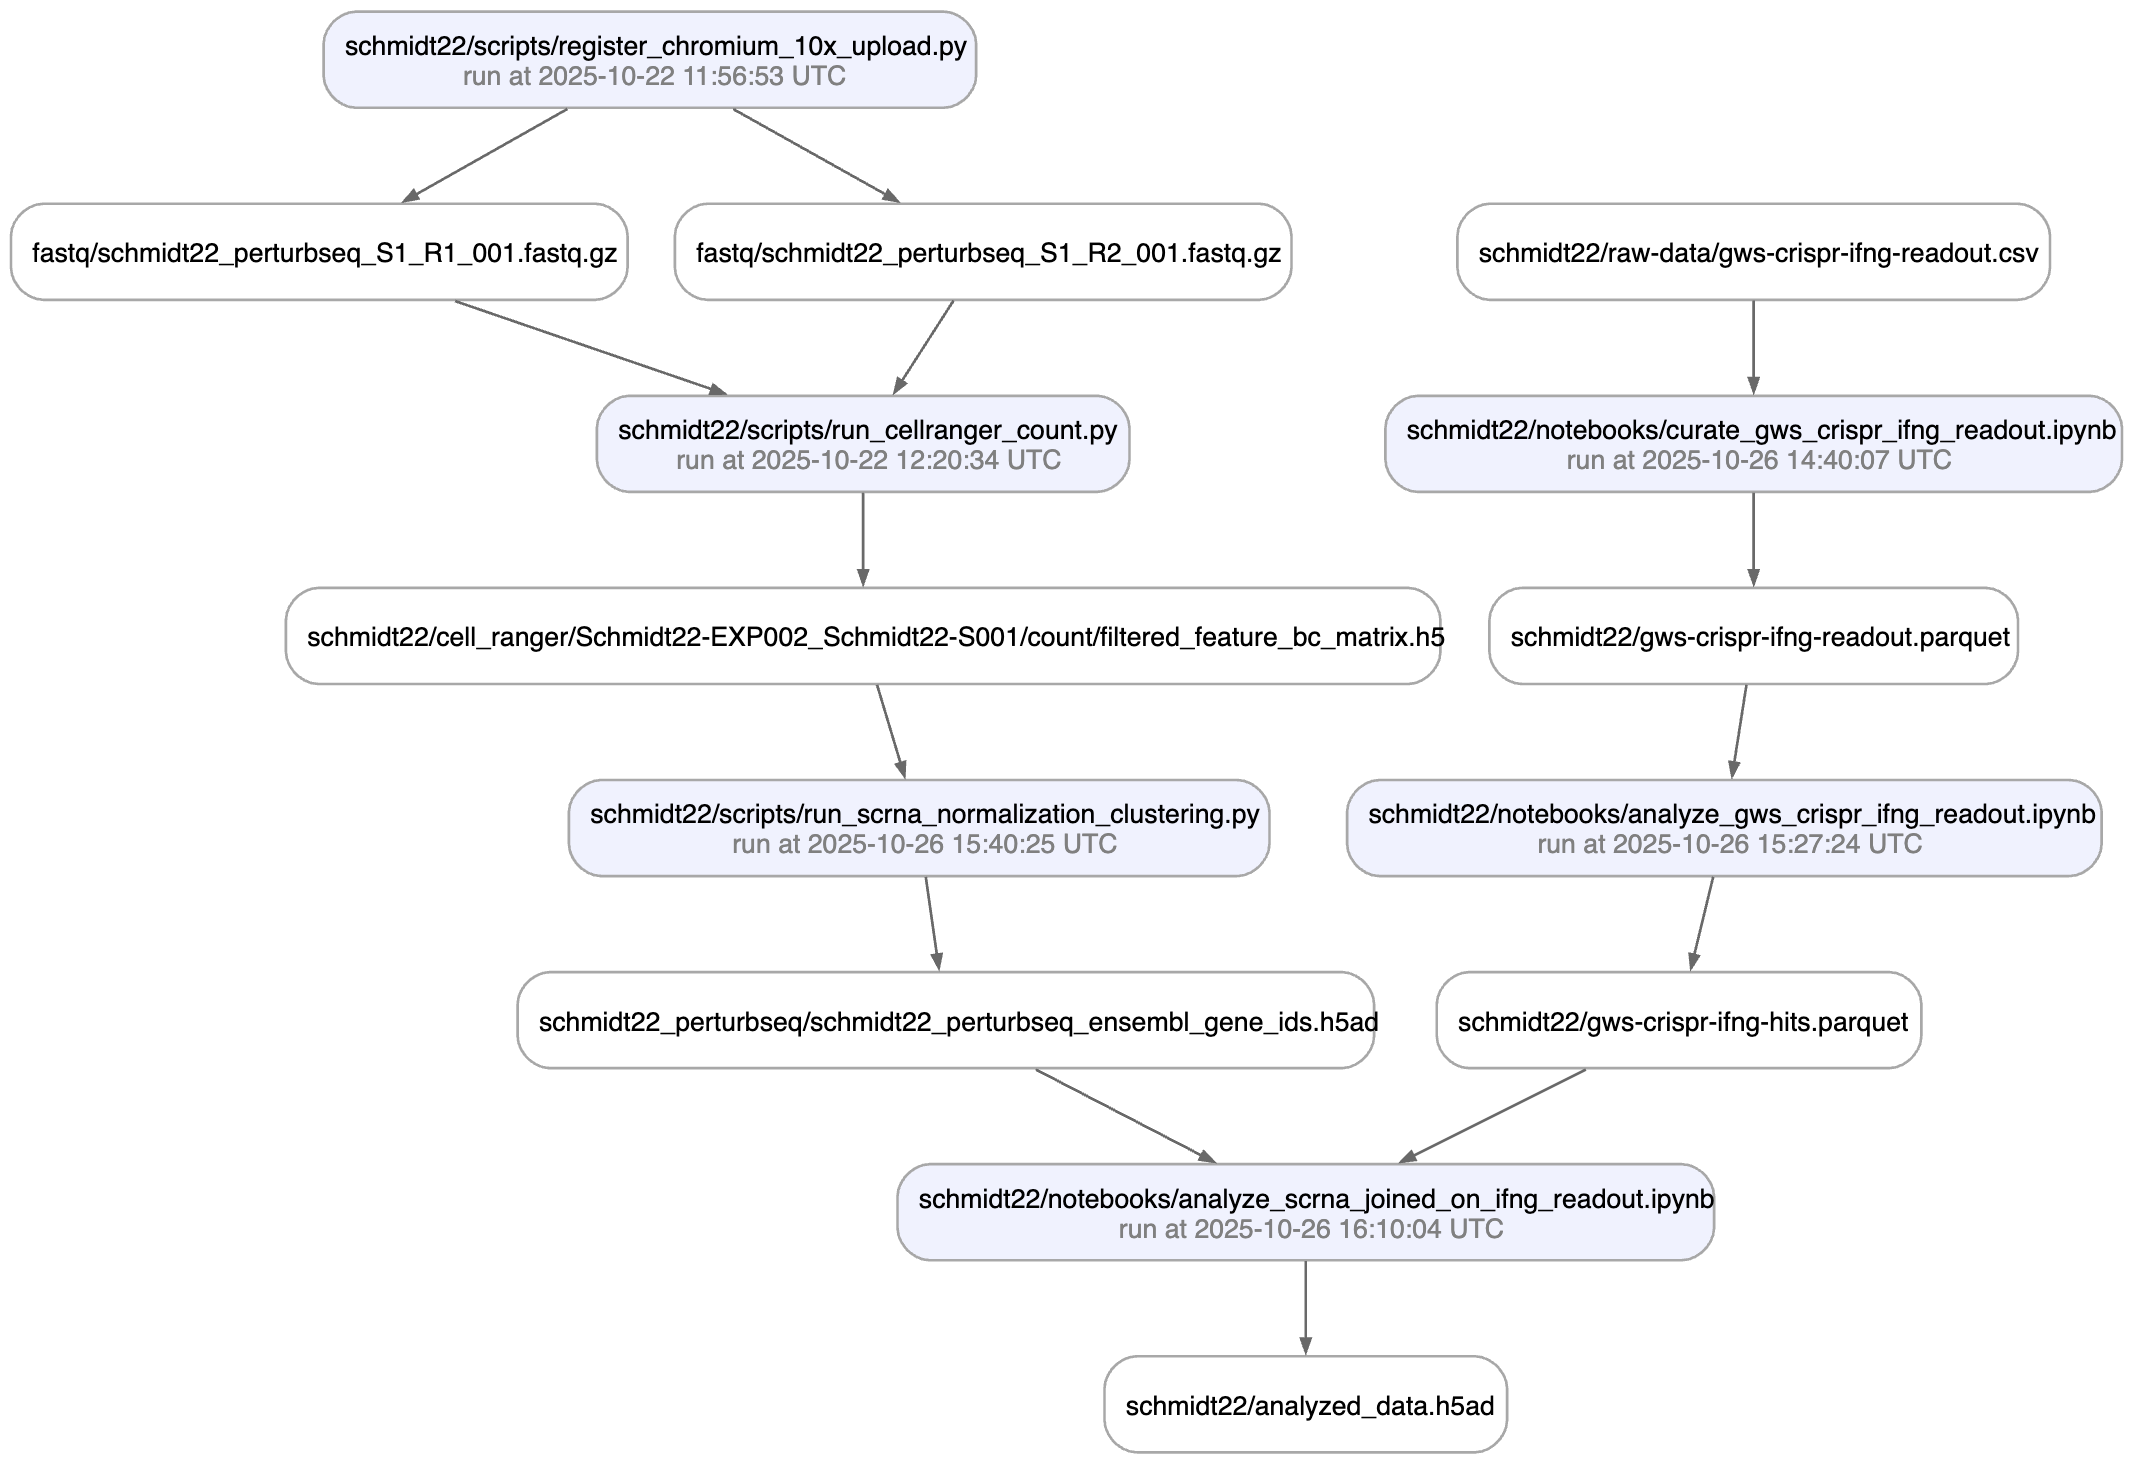
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
Annotate & query artifacts
To annotate and query by labels:
# define labels
my_label = ln.ULabel(name="My universal label").save()
my_project = ln.Project(name="My project label").save()

# annotate
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)

# query
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
To annotate & query by features:
from datetime import date

# define features
gc_content = ln.Feature(name="gc_content", dtype=float).save()
seq_date = ln.Feature(name="seq_date", dtype=date).save()

# annotate
artifact.features.set_values({
    gc_content: 0.55,
    seq_date: date.today(),
})

# query
ln.Artifact.filter(seq_date == date.today()).to_dataframe(include="features")
To query by auto-tracked metadata:
# by storage location and size
ln.Artifact.filter(storage__root=ln.settings.storage.root)
ln.Artifact.filter(size__gt=1e6).to_dataframe()

# by data lineage
ln.Artifact.filter(run=run).to_dataframe()
ln.Artifact.filter(run__transform=transform).to_dataframe()

# include more information in resulting dataframe
ln.Artifact.to_dataframe(include=["run__transform__key", "storage__root"])
Read more: docs.lamin.ai/organize or docs.lamin.ai/query-search
Create records & notes
You can create record types to model metadata for any entity:
# create record types
experiment_type = ln.Record(name="Experiments", is_type=True).save()
sample_type = ln.Record(name="Samples", is_type=True).save()

# create an experiment
experiment1 = ln.Record(
    name="Experiment 1",
    features={seq_date: date.today()},
    type=experiment_type
).save()

# create a sample that links to "Experiment 1" via a feature
experiment = ln.Feature(name="experiment", dtype=experiment_type).save()
sample1 = ln.Record(
    features={gc_content: 0.5, experiment: experiment1},
    type=sample_type
).save()

# export all experiments and all samples
experiment_type.to_dataframe()
sample_type.to_dataframe()
You can save markdown notes as records:
lamin save <topic>/<my-note.md>
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/manage-records.
Validate datasets
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "seq_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "seq_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
The simplest way to validate & annotate the content of the dataframe is the built-in schema valid_features:
ln.Feature(name="seq_str", dtype=str).save()  # define remaining features
ln.Feature(name="experiment_note", dtype=str).save()
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema="valid_features"  # validate columns against features
).save()
artifact.describe()
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate an AnnData, call:
import anndata as ad
import numpy as np
import pandas as pd

adata = ad.AnnData(
    X=np.ones((21, 10)),
    obs=pd.DataFrame({'cell_type_by_model': ['T cell', 'B cell', 'NK cell'] * 7}),
    var=pd.DataFrame(index=[f'ENSG{i:011d}' for i in range(10)])
)
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema="ensembl_gene_ids_and_valid_features_in_obs"
).save()
artifact.describe()
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
Use branching & versioning
LaminDB co-versions code and datasets for you.
If you edit and run the create_fasta.py script, you'll automatically create a new version of the transform and the sample.fasta artifact.
The edited script
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.run.transform.versions.to_dataframe()  # all versions of the transform that created the artifact
To isolate changes, create a contribution branch and switch to it as in git:
lamin switch -c my_branch
To merge a contribution branch into main, run:
lamin switch main  # switch to the main branch
lamin merge my_branch  # merge contribution branch into main
Read more: docs.lamin.ai/manage-changes.
Watch a mini video: youtu.be/rzRwcMj6-fc
Share datasets
To share data in a lineage-aware way, transfer objects from a source database to your default database:
db = ln.DB("laminlabs/lamindata")
artifact = db.Artifact.get(key="example_datasets/mini_immuno/dataset1.h5ad")
artifact.save()
This is zero-copy for the artifact's data in storage. Read more: docs.lamin.ai/transfer.
Manage ontologies
Plugin bionty gives you >20 public ontologies as SQLRecord registries. This was used to validate the ENSG ids in the adata just before.
import bionty as bt

bt.CellType.import_source()  # import the default ontology
bt.CellType.to_dataframe()   # your extensible cell type ontology in a simple registry
You can then create objects, e.g. for labeling, analogous to ULabel or Project:
t_cell = bt.CellType.get(name="T cell")
artifact.cell_types.add(t_cell)
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8
Run: uez3EVc (docs/README.ipynb)
├── uid: uez3EVcTiva8IXSs                transform: docs/README.ipynb (0000)
│   started_at: 2026-10-18 17:11:45 UTC  finished_at: 2026-10-18 17:11:48 UTC
│   status: completed
│   branch: main                         space: all
│   created_at: 2026-10-18 17:11:45 UTC  created_by: anonymous
└── environment: dQqStdV
    │ aiobotocore==3.9.2
    │ aiohappyeyeballs==2.7.1
    │ aiohttp==3.14.5
    │ aioitertools==0.13.0
    │ …
transform.describe() # context of the transform
Transform: docs/README.ipynb (0000) | description: LaminDB: Data management for traceable, multimodal AI ├── uid: CXwGmc7NoCXL0000 │ hash: ht2PV3mfbgVN0NS5Aji6cQ type: notebook │ branch: main space: all │ created_at: 2026-10-18 17:11:45 UTC created_by: anonymous └── source_code: │ # %% [markdown] │ # [](https://docs.lamin.ai) [![ … │ # │ # │ # │ # LaminDB is an open-source data management tool that makes it easy to query, tr … │ # Like git, LaminDB is a distributed system that runs anywhere and captures all … │ # This includes the data flow through models and analyses, the entities and note … │ # It takes about a minute to install LaminDB and create a database on your lapto … │ # │ # <details> │ # <summary>Why?</summary> │ # │ # 1. Untraceable results cannot be trusted, especially when non-verifiable tasks … │ # 2. Without effective access to multimodal data, models burn tokens or [fail en … │ # 3. Without governing changes to data akin to governing changes to software wit … │ # │ # Especially in life sciences, hard-to-verify tasks are abundant, data formats a … │ # │ # Traditional data infrastructure doesn't solve these issues because it was buil … │ # While modern SQL lakehouse solutions (Iceberg, Delta, DuckLake, Lakebase) exce … │ # LaminDB generalizes core lakehouse guarantees — ACID transactions, time travel … │ # │ # </details> │ # │ # <img width="800px" alt="lamindb-schematic" src="https://lamin-site-assets.s3.a … │ # │ # How? │ # │ # - **lineage** → trace results across agent sessions, notebooks, scripts & work … │ …
To track a workflow, decorate a function:
import lamindb as ln

@ln.flow()
def create_fasta(fasta_file: str = "sample.fasta"):
    open(fasta_file, "w").write(">seq1\nACGT\n")    # create dataset
    ln.Artifact(fasta_file, key=fasta_file).save()  # save dataset

if __name__ == "__main__":
    pass
Beyond what you get for scripts & notebooks, this automatically tracks function & CLI params and integrates well with established Python workflow managers: docs.lamin.ai/track. To integrate advanced bioinformatics pipeline managers like Nextflow, see docs.lamin.ai/pipelines.
A richer example.
Here is a re-construction of the project of Schmidt et al. (Science, 2022):
A phenotypic CRISPRa screening result is integrated with scRNA-seq data. Here is the result of the screen input:
Annotate & query artifacts
To annotate and query by labels:
# define labels
my_label = ln.ULabel(name="My universal label").save()
my_project = ln.Project(name="My project label").save()

# annotate
artifact.ulabels.add(my_label)
artifact.projects.add(my_project)

# query
ln.Artifact.filter(ulabels=my_label, projects=my_project).to_dataframe()
! tip: pass `type` to map ulabel into a type hierarchy
! tip: pass `type` to map project into a type hierarchy
| uid | key | description | suffix | kind | otype | size | hash | n_files | n_observations | ... | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | storage_id | run_id | schema_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||||
| 1 | LYsrykT8jjIQteqa0000 | sample.fasta | None | .fasta | None | None | 11 | 83rEPcAoBHmYiIuyBYrFKg | None | None | ... | True | False | 2026-10-18 17:11:45.179000+00:00 | 1 | 1 | 1 | 1 | 1 | None | 1 |
1 rows × 22 columns
To annotate & query by features:
from datetime import date

# define features
gc_content = ln.Feature(name="gc_content", dtype=float).save()
seq_date = ln.Feature(name="seq_date", dtype=date).save()

# annotate
artifact.features.set_values({
    gc_content: 0.55,
    seq_date: date.today(),
})

# query
ln.Artifact.filter(seq_date == date.today()).to_dataframe(include="features")
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
| uid | key | gc_content | seq_date | |
|---|---|---|---|---|
| id | ||||
| 1 | LYsrykT8jjIQteqa0000 | sample.fasta | 0.55 | 2026-10-18 |
To query by auto-tracked metadata:
# by storage location and size
ln.Artifact.filter(storage__root=ln.settings.storage.root)
ln.Artifact.filter(size__gt=1e6).to_dataframe()

# by data lineage
ln.Artifact.filter(run=run).to_dataframe()
ln.Artifact.filter(run__transform=transform).to_dataframe()

# include more information in resulting dataframe
ln.Artifact.to_dataframe(include=["run__transform__key", "storage__root"])
| uid | key | run__transform__key | storage__root | |
|---|---|---|---|---|
| id | ||||
| 1 | LYsrykT8jjIQteqa0000 | sample.fasta | docs/README.ipynb | /home/runner/work/lamindb/lamindb/storage |
Read more: docs.lamin.ai/organize or docs.lamin.ai/query-search
Create records & notes
You can create record types to model metadata for any entity:
# create record types
experiment_type = ln.Record(name="Experiments", is_type=True).save()
sample_type = ln.Record(name="Samples", is_type=True).save()

# create an experiment
experiment1 = ln.Record(
    name="Experiment 1",
    features={seq_date: date.today()},
    type=experiment_type
).save()

# create a sample that links to "Experiment 1" via a feature
experiment = ln.Feature(name="experiment", dtype=experiment_type).save()
sample1 = ln.Record(
    features={gc_content: 0.5, experiment: experiment1},
    type=sample_type
).save()

# export all experiments and all samples
experiment_type.to_dataframe()
sample_type.to_dataframe()
! tip: pass `type` to map record into a type hierarchy
! tip: pass `type` to map record into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
→ exporting 1 records of 'Experiments'
→ exporting 1 records of 'Samples'
| experiment | gc_content | __lamindb_record_uid__ | __lamindb_record_name__ | |
|---|---|---|---|---|
| __lamindb_record_id__ | ||||
| 4 | Experiment 1 | 0.5 | sn3LdgxA05NKwP5y | None |
You can save markdown notes as records:
lamin save <topic>/<my-note.md>
To load a record back as a markdown file, run:
lamin load https://lamin.ai/laminlabs/lamindata/record/mNDJgWFrkWQVW3ox
Watch a mini video: youtu.be/NRzVQXJaRH8
Read more: docs.lamin.ai/manage-records.
Validate datasets
Here is how you ingest a DataFrame:
import pandas as pd

df = pd.DataFrame({
    "seq_str": ["ACGT", "TGCA"],
    "gc_content": [0.55, 0.54],
    "experiment_note": ["Looks great", "Ok"],
    "seq_date": [date(2025, 10, 24), date(2025, 10, 25)],
})
ln.Artifact.from_dataframe(df, key="my_datasets/sequences.parquet").save()  # no validation
Artifact(uid='7cad5URwBc14TOdh0000', key='my_datasets/sequences.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame', size=3290, hash='D8zrEfQMYHaFYwFBYgaedg', n_files=None, n_observations=2, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-10-18 17:11:49 UTC, is_locked=False, version_tag=None, is_latest=True)
The simplest way to validate & annotate the content of the dataframe is the built-in schema valid_features:
ln.Feature(name="seq_str", dtype=str).save()  # define remaining features
ln.Feature(name="experiment_note", dtype=str).save()
artifact = ln.Artifact.from_dataframe(
    df,
    key="my_datasets/sequences.parquet",
    schema="valid_features"  # validate columns against features
).save()
artifact.describe()
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map feature into a type hierarchy
! tip: pass `type` to map schema into a type hierarchy
→ returning artifact with same hash: Artifact(uid='7cad5URwBc14TOdh0000', key='my_datasets/sequences.parquet', description=None, suffix='.parquet', kind='dataset', otype='DataFrame', size=3290, hash='D8zrEfQMYHaFYwFBYgaedg', n_files=None, n_observations=2, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-10-18 17:11:49 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an input, use: ln.Artifact.get()
→ loading artifact into memory for validation
Artifact: my_datasets/sequences.parquet (0000)
├── uid: 7cad5URwBc14TOdh0000  kind: dataset
│   otype: DataFrame           hash: D8zrEfQMYHaFYwFBYgaedg
│   size: 3.2 KB               branch: main
│   space: all                 created_at: 2026-10-18 17:11:49 UTC
│   created_by: anonymous      n_observations: 2
│   schema: valid_features
├── storage/path: /home/runner/work/lamindb/lamindb/storage/.lamindb/7cad5URwBc14TOdh0000.parquet
└── Dataset features
    └── columns (4)
        experiment_note                str
        gc_content                     float
        seq_date                       date
        seq_str                        str
You can filter for datasets by schema and then launch distributed queries or batch load distributed datasets. For tables, see: docs.lamin.ai/tables. For arrays, see: docs.lamin.ai/arrays.
Watch a mini video: youtu.be/Ji6E7hTnReQ
To validate an AnnData, call:
import anndata as ad
import numpy as np
import pandas as pd

adata = ad.AnnData(
    X=np.ones((21, 10)),
    obs=pd.DataFrame({'cell_type_by_model': ['T cell', 'B cell', 'NK cell'] * 7}),
    var=pd.DataFrame(index=[f'ENSG{i:011d}' for i in range(10)])
)
artifact = ln.Artifact.from_anndata(
    adata,
    key="my_datasets/scrna.h5ad",
    schema="ensembl_gene_ids_and_valid_features_in_obs"
).save()
artifact.describe()
! tip: pass `type` to map schema into a type hierarchy
! tip: pass `type` to map schema into a type hierarchy
→ loading artifact into memory for validation
/opt/hostedtoolcache/Python/3.14.8/x64/lib/python3.14/functools.py:982: ImplicitModificationWarning: Transforming to str index.
  return dispatch(args[0].__class__)(*args, **kw)
✓ created 1 Organism record from Bionty matching ontology_id: 'NCBITaxon:9606'
! no values were validated for columns!
✓ added 2 records from_public with bionty.Gene for "columns": 'ENSG00000000003', 'ENSG00000000005'
→ returning schema with same hash: Schema(uid='0000000000000000', is_type=False, name='valid_features', description=None, n_members=None, coerce=None, flexible=True, itype='Feature', otype=None, suffix=None, hash='kMi7B_N88uu-YnbTLDU-DA', minimal_set=True, ordered_set=False, maximal_set=False, branch_id=1, created_on_id=1, space_id=1, created_by_id=1, run_id=None, type_id=None, created_at=2026-10-18 17:11:49 UTC, is_locked=False)
Artifact: my_datasets/scrna.h5ad (0000)
├── uid: pbPu6Up9lyrnijz90000                                   kind: dataset
│   otype: AnnData                                              hash: uQIl7QQgfwlLFOXuoIzkwg
│   size: 24.0 KB                                               branch: main
│   space: all                                                  created_at: 2026-10-18 17:11:54 UTC
│   created_by: anonymous                                       n_observations: 21
│   schema: anndata_ensembl_gene_ids_and_valid_features_in_obs
├── storage/path: /home/runner/work/lamindb/lamindb/storage/.lamindb/pbPu6Up9lyrnijz90000.h5ad
└── Dataset features
    ├── obs (None)
    └── var.T (2 bionty.Gene.ensembl…
        TNMD                           num
        TSPAN6                         num
To validate a SpatialData or any other array-like dataset, you need to construct a Schema. You can do this by composing simple pandera-style schemas: docs.lamin.ai/curate.
Use branching & versioning
LaminDB co-versions code and datasets for you.
If you edit and run the create_fasta.py script, you’ll automatically create a new version of the transform and the sample.fasta artifact.
The edited script
# create_fasta.py
import lamindb as ln

ln.track()
open("sample.fasta", "w").write(">seq1\nTGCA\n")  # a new sequence
ln.Artifact("sample.fasta", key="sample.fasta", features={"experiment": "Experiment 1"}).save()  # annotate with the new experiment
ln.finish()
→ found notebook docs/README.ipynb, making new version -- anticipating changes
→ created Transform('CXwGmc7NoCXL0001', key='docs/README.ipynb'), started new Run('9Mcm4PMZsM8AT7xc') at 2026-10-18 17:11:54 UTC
• tip: to identify the notebook across renames, pass the uid: ln.track("CXwGmc7NoCXL")
→ creating new artifact version for key 'sample.fasta' in storage '/home/runner/work/lamindb/lamindb/storage'
! cells [(4, 6), (16, 18)] were not run consecutively
→ returning artifact with same hash: Artifact(uid='FPKoxHPZrOrqoM4w0000', key=None, description='Report of run uez3EVcTiva8IXSs', suffix='.html', kind='__lamindb_run__', otype=None, size=339640, hash='ZkeRFTf2Kl3mETP0Tj6q6A', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-10-18 17:11:48 UTC, is_locked=False, version_tag=None, is_latest=True); to track this artifact as an input, use: ln.Artifact.get()
! run was not set on Artifact(uid='FPKoxHPZrOrqoM4w0000', key=None, description='Report of run uez3EVcTiva8IXSs', suffix='.html', kind='__lamindb_run__', otype=None, size=339640, hash='ZkeRFTf2Kl3mETP0Tj6q6A', n_files=None, n_observations=None, extra_data=None, branch_id=1, created_on_id=1, space_id=1, storage_id=1, run_id=None, schema_id=None, created_by_id=1, created_at=2026-10-18 17:11:48 UTC, is_locked=False, version_tag=None, is_latest=True), setting to current run
! updated description from Report of run uez3EVcTiva8IXSs to Report of run 9Mcm4PMZsM8AT7xc
! returning transform with same hash & key: Transform(uid='CXwGmc7NoCXL0000', key='docs/README.ipynb', description='LaminDB: Data management for traceable, multimodal AI', kind='notebook', hash='ht2PV3mfbgVN0NS5Aji6cQ', reference=None, reference_type=None, environment=None, plan=None, branch_id=1, created_on_id=1, space_id=1, run_id=None, created_by_id=1, created_at=2026-10-18 17:11:45 UTC, is_locked=False, version_tag=None, is_latest=False)
! run was not set on Transform(uid='CXwGmc7NoCXL0000', key='docs/README.ipynb', description='LaminDB: Data management for traceable, multimodal AI', kind='notebook', hash='ht2PV3mfbgVN0NS5Aji6cQ', reference=None, reference_type=None, environment=None, plan=None, branch_id=1, created_on_id=1, space_id=1, run_id=None, created_by_id=1, created_at=2026-10-18 17:11:45 UTC, is_locked=False, version_tag=None, is_latest=False), setting to current run
• new latest Transform version is: CXwGmc7NoCXL0000
→ finished Run('9Mcm4PMZsM8AT7xc') after 1s at 2026-10-18 17:11:55 UTC
artifact_latest = ln.Artifact.get(key="sample.fasta")  # pass version for a previous version: ln.Artifact.get(key="sample.fasta", version="1.0")
artifact_latest.versions.to_dataframe()                # all versions of that artifact
artifact_latest.run.transform.versions.to_dataframe()  # all versions of the transform that created the artifact
| uid | key | description | kind | source_code | hash | reference | reference_type | version_tag | is_latest | is_locked | created_at | branch_id | created_on_id | space_id | environment_id | plan_id | run_id | created_by_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | |||||||||||||||||||
| 1 | CXwGmc7NoCXL0000 | docs/README.ipynb | LaminDB: Data management for traceable, multim... | notebook | # %% [markdown]\n# [ # import the default ontology
bt.CellType.to_dataframe() # your extensible cell type ontology in a simple registry
✓ import is completed!
! truncated query result to limit=20 CellType objects
| uid | name | ontology_id | abbr | synonyms | description | is_locked | created_at | branch_id | created_on_id | space_id | created_by_id | run_id | source_id | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| id | ||||||||||||||
| 3533 | 1ChUsEzDZXWW4B | beam B cell, human | CL:7770006 | None | nan | A Trabecular Meshwork Cell Within The Eye'S Tr... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3532 | 5xoxfxIf7WrLdU | beam cell | CL:7770005 | None | nan | A Trabecular Meshwork Cell That Is Part Of The... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3531 | 2j5mhhFoV2vBDV | suprabasal cell | CL:7770004 | None | nan | An Epithelial Cell That Resides In The Layer(S... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3530 | RBCFqAmkM1oaaZ | beam A cell | CL:7770003 | None | nan | A Beam Cell Within The Eye'S Trabecular Meshwo... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3529 | 79Ow7BGPRP018I | juxtacanalicular tissue cell | CL:7770002 | None | nan | A Trabecular Meshwork Cell Of The Juxtacanalic... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3528 | 4qJMS0d5FyIXQK | OB FRMD7 GABA GABAergic neuron (Primate) | CL:4310148 | None | OB FRMD7 GABA | A Gabaergic Neuron Of The Primates Brain. Thes... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3527 | 6iU1Q2FIIkrgND | OB Dopa-GABA OB-Dopa-GABA (Primate) | CL:4310147 | None | OB Dopa-GABA | A Ob-Dopa-Gaba Of The Primates Brain. These Ce... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3526 | 100qUn3IH1Ksw2 | AMY-SLEA-BNST GABA GABAergic interneuron (Prim... | CL:4310146 | None | AMY-SLEA-BNST GABA | A Gabaergic Interneuron Of The Primates Brain.... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3525 | QJ8929f49Ncfrf | AMY-SLEA-BNST D1 GABA GABAergic interneuron (P... | CL:4310145 | None | AMY-SLEA-BNST D1 GABA | A Gabaergic Interneuron Of The Primates Brain.... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3524 | 2RruqlADchF4D3 | VTR-HTH Glut glutamatergic neuron of the basal... | CL:4310144 | None | F M Glut|VTR-HTH Glut | A Glutamatergic Neuron Of The Basal Ganglia Of... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3523 | 44qrwytpXARNMz | ZI-HTH GABA GABAergic interneuron (Primate) | CL:4310143 | None | ZI-HTH GABA | A Gabaergic Interneuron Of The Primates Brain.... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3522 | 3dVBqPp88IUIib | STRv D2 MSN nucleus accumbens shell and olfact... | CL:4310138 | None | STRv D2 MSN|D2-Shell/OT | A Nucleus Accumbens Shell And Olfactory Tuberc... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3521 | 4RRtGKe1oGoVGV | STRv D1 NUDAP MSN D1-NUDAP medium spiny neuron... | CL:4310137 | None | D1-NUDAP|STRv D1 NUDAP MSN | A D1-Nudap Medium Spiny Neuron Of The Primates... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3520 | 1Tw4GET7C0W2Az | STRv D1 MSN nucleus accumbens shell and olfact... | CL:4310136 | None | D1-Shell/OT|STRv D1 MSN | A Nucleus Accumbens Shell And Olfactory Tuberc... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3519 | 3taUBSHOL3ffx3 | STR Cholinergic GABA striatal cholinergic-GABA... | CL:4310135 | None | STR Cholinergic GABA | A Striatal Cholinergic-Gabaergic Neuron Of The... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3518 | 2OzOl5s6HeWYYM | STRd D2 Striosome MSN striosomal D2 medium spi... | CL:4310134 | None | D2-Striosome|STRd D2 Striosome MSN | A Striosomal D2 Medium Spiny Neuron Of The Pri... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3517 | 3ZypczMtxf4KQu | STRd D2 StrioMat Hybrid MSN indirect pathway m... | CL:4310133 | None | STRd D2 StrioMat Hybrid MSN | A Indirect Pathway Medium Spiny Neuron Of The ... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3516 | 2Mk5r9Xsi24yLc | STRd D2 Matrix MSN matrix D2 medium spiny neur... | CL:4310132 | None | D2-Matrix|STRd D2 Matrix MSN | A Matrix D2 Medium Spiny Neuron Of The Primate... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3515 | 5e4cn19DcnuNH0 | STR D1D2 Hybrid MSN D1/D2-hybrid medium spiny ... | CL:4310131 | None | STR D1D2 Hybrid MSN|D1/D2 Hybrid | A D1/D2-Hybrid Medium Spiny Neuron Of The Prim... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
| 3514 | 67anmsVZv7HmGa | STRd D1 Striosome MSN striosomal D1 medium spi... | CL:4310130 | None | D1-Striosome|STRd D1 Striosome MSN | A Striosomal D1 Medium Spiny Neuron Of The Pri... | False | 2026-10-18 17:12:03.202000+00:00 | 1 | 1 | 1 | 1 | None | 26 |
You can then create objects, e.g. for labeling, analogous to ULabel or Project:
t_cell = bt.CellType.get(name="T cell")
artifact.cell_types.add(t_cell)
Read more: docs.lamin.ai/manage-ontologies.
Watch a mini video: youtu.be/3vpWjHj3Kw8